About the project
# Nigerian Accented Speech-to-Text Model
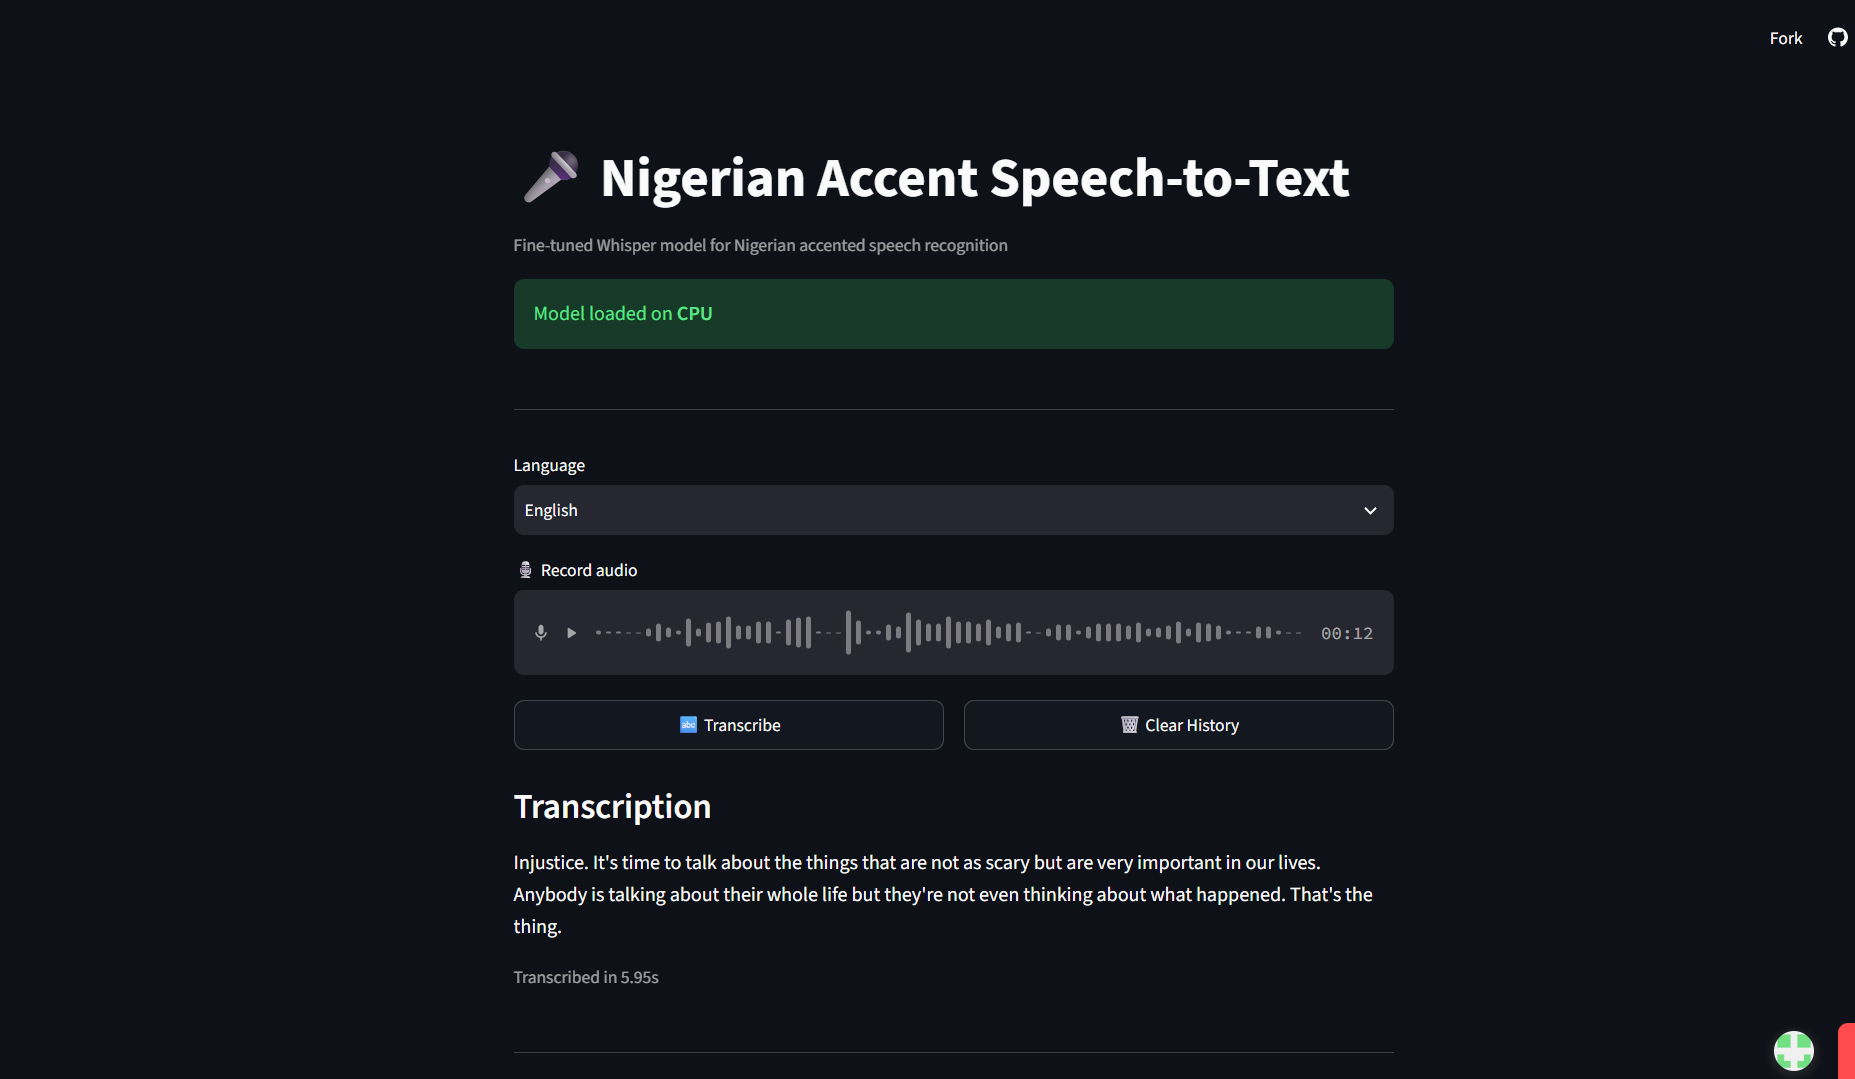
A fine-tuned version of OpenAI's Whisper model, trained to better understand Nigerian-accented English speech.
## What It Does
Most speech-to-text (STT) systems struggle with Nigerian accents because they're mainly trained on American or British English. This project fine-tunes Whisper on Nigerian-accented voice data to improve transcription accuracy for Nigerian speakers.
## How It Was Built
- **Base model:** `openai/whisper-small`
- **Training data:** Nigerian-accent subset of the Mozilla Common Voice dataset (`benjaminogbonna/nigerian_common_voice_dataset`)
- **Language:** Python
- **Core libraries:**
- `torch` (PyTorch) — model training, tensor operations, GPU handling
- `transformers` (Hugging Face) — Whisper model, tokenizer, and feature extractor
- `datasets` (Hugging Face) — loading and splitting the training data
- `huggingface_hub` — authenticating and downloading models/datasets
- **Evaluation:**
- `evaluate` — scoring model outputs
- `jiwer` — calculating Word Error Rate (WER) and Character Error Rate (CER)
- `rapidfuzz` — string alignment used internally by `jiwer`
## Why It Matters
Accurate Nigerian-accented STT can support:
- Medical documentation (transcribing doctor-patient conversations)
- Customer service and voice assistants
- Call analysis for sales/support quality
- Video captioning and searchable media
- Voice dictation in apps and internal tools
## What's Next
The model currently only covers Nigerian-accented **English**. Future work will expand it to **Nigerian Pidgin, Yoruba, and Igbo**, to make speech-to-text technology more inclusive of Nigeria's language diversity.
 Joshua Oluwatigbemileke AgboolaAI ML Developer
 RAIN